Download this notebook from github.
Extending xclim
xclim tries to make it easy for users to add their own indicators. The following goes into details on how to create compute functions and document them so that xclim can parse most of the metadata directly. We then explain the multiple ways new Indicators can be created and how we can regroup and structure them in IndicatorCollections.
Central to xclim are the Indicators, objects computing some statistic or function over climate variables, but xclim also provides many other modules.
This introduction will focus on the Indicator part of xclim and how one can extend it by implementing new ones.
Indicators and compute functions
Internally and in the documentation, xclim makes a distinction between “indicators” and their compute functions.
index-like compute function
A python function accepting DataArrays and other parameters (usually built-in types)
Returns one or several DataArrays.
Handles the units : checks input units (via a decorator) and set proper CF-compliant output units. But doesn’t usually prescribe specific units, the output will at minimum have the proper dimensionality.
Usually, performs no other checks or set any (non-unit) metadata.
May have a documentation following a certain template so that parsing it is easier
Accessible through xclim.compute.
indicator
An instance of a subclass of
xclim.core.indicator.Indicatorthat wraps around the previous index-like compute function (stored in itscomputeproperty).Returns one or several DataArrays, or a Dataset, according to the
as_datasetglobal option (see xclim.set_options).Handles missing values, performs input data checks and metadata checks (see usage).
Always outputs data in the same units.
Adds (dynamically generated) metadata to the output after computation. Including
historyandxclim_descriptionin addition to user-provided attributes.Accessible through xclim.indicators.
Most metadata stored in the Indicators is parsed from the underlying index documentation, so defining indices with complete documentation and an appropriate signature helps the process. The two next sections go into details on the definition of both objects.
Call sequence
The following graph shows the steps done when calling an Indicator. Attributes and methods of the Indicator object relating to those steps are listed on the right side.

Defining new index-like compute functions
The annotated example below shows the general template to be followed when defining a compute function to be wrapped by the Indicator class. The target attributes of the indicator instance that would be created from this function are added to the figure for reference.
Note that these standards are not all required. Problems in parsing will not raise errors at runtime, but might raise warnings and will result in Indicators with poorer metadata than expected by most users, especially those that dynamically use them in other applications where the code is inaccessible, like web services.
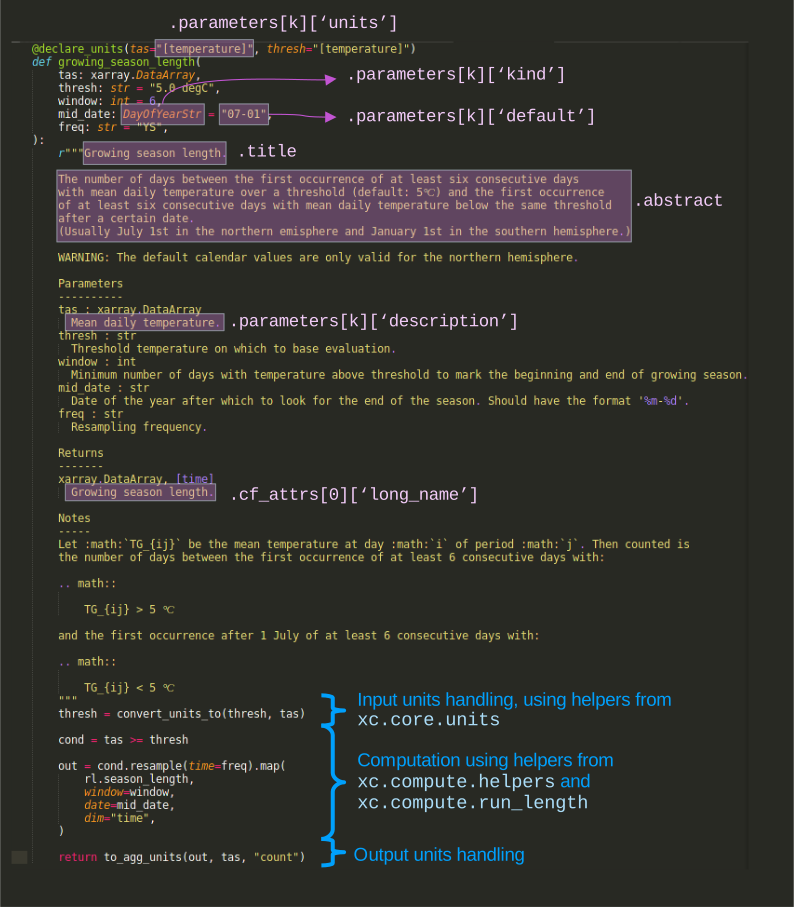
The following code is another example.
[ ]:
import xarray as xr
from IPython.display import Code, display

import xclim
from xclim.compute.generic import count_occurrences
from xclim.core import Condition, Freq, Quantified
from xclim.core.units import convert_units_to, declare_units, to_agg_units


@declare_units(tasmax="[temperature]", thresh="[temperature]")
def tx_days_compare(tasmax: xr.DataArray, thresh: Quantified = "0 degC", condition: Condition = ">", freq: Freq = "YS"):
    r"""
    Number of days where maximum daily temperature is above or under a threshold.

    The daily maximum temperature is compared to a threshold using a given operator and the number
    of days where the condition is true is returned.

    It assumes a daily input.

    Parameters
    ----------
    tasmax : xarray.DataArray
        Maximum daily temperature.
    thresh : str
        Threshold temperature to compare to.
    condition : {'>', '<'}
        The condition to verify.
        # A fixed set of choices can be imposed. Only strings, numbers, booleans or None are accepted.
    freq : str
        Resampling frequency.

    Returns
    -------
    xarray.DataArray, [temperature]
        Maximum value of daily maximum temperature.

    Notes
    -----
    Let :math:`TX_{ij}` be the maximum temperature at day :math:`i` of period :math:`j`. Then the maximum
    daily maximum temperature for period :math:`j` is:

    .. math::

        TXx_j = max(TX_{ij})

    References
    ----------
    :cite:cts:`smith_citation_2020`
    """
    thresh = convert_units_to(thresh, tasmax)
    out = count_occurrences(tasmax, condition, thresh, freq)
    return to_agg_units(out, tasmax, "count")
Naming and conventions
Variable names should correspond to CMIP6 variables or CMIP7 physical parameters, whenever possible. The file xclim/data/variables.yml lists all variables that xclim can use when generating indicators.
Annotations
The example above makes use of Typing vars from xclim.core to annotate the signature of the function. This is recommended, while not necessary. It helps the Indicator wrap the function with more meaningful metadata.
Generic functions for common operations
The xclim.compute.generic submodule contains generic index-like functions for common computations (like count_occurrences or statistics), inspired by clix-meta. In order to reduce duplicate code, their use is recommended when possible inside xclim. As previously said, the units handling has to be made explicitly when non-trivial,
xclim.core.units also exposes a few helpers for that (like convert_units_to, to_agg_units or rate2amount).
Documentation
As shown in both example, a certain level of convention is best followed when writing the docstring of the index function. The general structure follows the NumpyDoc conventions, and some fields might be parsed when creating the indicator (see the image above and the section below). If you are contributing to the xclim codebase, when adding a citation to the docstring, this is best done by adding that reference to the references.bib file and then citing it using its label with the
:cite:cts: directive (or one of its variant). See the contributing docs.
Defining new indicators
xclim’s Indicators are instances of (subclasses of) xclim.core.indicator.Indicator. While they are the central to xclim, their construction can be somewhat tricky as a lot happens backstage. Essentially, they act as self-aware functions, taking a set of input variables (DataArrays) and parameters (usually strings, integers or floats), performing some health checks on them and returning one or multiple DataArrays, with CF-compliant (and potentially translated) metadata attributes, masked
according to a given missing value set of rules. They define the following key attributes:
the
identifier, as string that uniquely identifies the indicator, usually all caps.the
realm, one of “atmos”, “land”, “seaIce” or “ocean”, classifying the domain of use of the indicator.the
computefunction that returns one or more DataArrays, the “index”,the
cfcheckanddatacheckmethods that make sure the inputs are appropriate and valid.the
missingfunction that masks elements based on null values in the input.all metadata attributes that will be attributed to the output and that document the indicator:
Indicator-level attribute are :
title,abstract,keywords,referencesandnotes.Output variables attributes always include
var_nameandunits, plus any other attributes. Usually, indicator have CF attributes likestandard_name,long_name,cell_methods,descriptionorcomment.
Output variables metadata are regrouped in Indicator.outputs and input parameters are documented in Indicator.parameters.
A particularity of Indicators is that each instance corresponds to a single class: when creating a new indicator, a new class is automatically created. This is done for easy construction of indicators based on others, like shown further down.
See the class documentation for more info on the meaning of each attribute. The indicators module contains over 50 examples of indicators to draw inspiration from.
Identifier vs python name
An indicator’s identifier is not the same as the name it has within the python module. For example, xclim.atmos.relative_humidity has hurs as its identifier. As explained below, indicator can be accessed through xclim.core.indicator.registry with their identifier.
Metadata parsing vs explicit setting
As explained above, most metadata can be parsed from the compute function’s signature and docstring. Otherwise, it can always be set when creating a new Indicator instance or a new subclass. When creating an indicator, output metadata attributes may be given as strings (or list of strings for multi output) for convenience. However, they are stored in the attrs attribute of the instance, a list of xclim.core.indicator.Output dict-like objects.
Internationalization of metadata
xclim offers the possibility to translate the main Indicator metadata field and can automatically add the translations to the outputs. The mechanism is explained in the Internationalization page. French translation is usually already available for built-in indicators.
Inputs and checks
xclim decides which input arguments of the indicator’s call function are considered variables and which are parameters using the annotations of the underlying index (the compute method). Arguments annotated with the xarray.DataArray type are considered variables and can be read from the dataset passed in ds.
Indicator creation
There are three ways of creating indicators:
By initializing an existing indicator (sub)class
From a Yaml file, when creating an
IndicatorCollection
The first method is best when defining indicators in scripts or external modules and is explained here. The second is explained further down and in the submodule doc.
Creating a new indicator that simply modifies some metadata output of an existing one is a simple call to the parent’s copy:
[ ]:
# An indicator based on tg_mean, but returning Celsius and fixed on annual resampling
tg_mean_c = xclim.atmos.tg_mean.copy(
    identifier="tg_mean_c",
    units="degC",
    title="Mean daily mean temperature but in degC",
    parameters=dict(freq="YS"),  # We inject the freq arg.
)
[ ]:
display(Code(tg_mean_c.__doc__, language="rst"))
tg_mean_c is the exact same as atmos.tg_mean (same output variable name and attributes, same compute function), but outputs the result in Celsius instead of Kelvins, has a different title and removes control over the freq argument, resampling to “YS”. The identifier keyword is here needed in order to differentiate the new indicator from tg_mean itself in the indicator registry. We could also have passed register=False to skip registering this new indicator, allowing for
an empty identifier.
By default, indicator classes are registered in xclim.core.indicator.registry, using their identifier. If identifier it wasn’t given in the new indicator, a warning would have been raised and tg_mean would have been replaced by the new indicator in the registry.
Indicator Collections
xclim gives users the ability to regroup indicators into IndicatorCollection. This can be used for example to tailor existing indicators with predefined thresholds without having to rewrite them. They are usually initialized from YAML file configuration, which allows grouping indicator definitions in a static, versionable, external file.
Within xclim itself, the concept is used to make “virtual submodules” exposing indicators approximating the ones developed in other projects : icclim, ANUCLIM and clix-meta. xclim is open to contributions of new indicators and library mappings!
This notebook serves as an example of how one might go about creating their own library of mapped indicators via a YAML file.
This idea is based on the YAML syntax proposed by clix-meta, expanded to xclim’s needs. The full documentation on that syntax is here. This notebook shows an example of different complexities of indicator creation. It creates a minimal python module defining a compute function, creates a YAML file with the metadata for several indicators and then parses it into xclim.
[ ]:
# These variables were generated by a hidden cell above that syntax-colored them.
print("Content of example.py :")
display(Code(pydata, language="python"))
print("\n\nContent of example.yml :")
display(Code(ymldata, language="yaml"))
print("\n\nContent of example.fr.json :")
display(Code(jsondata, language="json"))
example.yml created a module of seven (7) indicators and one (1) base indicator class.
Indicators are always derived from a subclass of xclim.core.indicator.Indicator. The decision of which one to use is set through the base argument. This can have multiple forms:
A name referring to the identifier in the indicator registry
xclim.core.indicator.registryor to a name in the base class registryxclim.core.indicator.base_registryA qualified name relative to
xclim.indicators(see first indicator below) or a full qualified name of something to import dynamically.The name of another indicator or class declared within the current collection.
When unset, the
basedefaults to the one defined collection-wide or toxclim.core.indicator.Daily.
RX1dayis derived from xclim.indicators.atmos.max_1day_precipitation_amount, with an updatedlong_nameand an injected argument; Itsindexerarg is now set to only compute over May to September.RX5day_canopyis based onregistry['max_n_day_precipitation_amount'], changed thelong_nameand injects thewindowandfreqarguments.It also requests a different variable than the original indicator :
prveginstead ofpr. Asxclimdoesn’t know aboutprveg, a definition is given in thevariablessection.
R75pdaysis based onregistry['days_over_precip_thresh'], injects thethreshargument and changes the description of theperargument.first_frost_dayis a more complex example. As there were nobase:entry, theDailyclass serves as a base by default. This class doesn’t do much, so a lot has to be given explicitly:A compute function name if given. Here it refers a “generic” function (in
xclim.compute.generic), which means it doesn’t provide any pertinent metadata, but it handles the units.Thus, output metadata fields are given
Some parameters are injected (they will not appear on the indicator’s signature), the default for
freqis modified, but left as an argument.The input variable
datais mapped to a known variable. “Generic” functions need to be told what units to expect, so we tellxclimthat thedataargument is minimum daily temperature. This will activate the proper units check and CF-compliance checks within the indicator class.
R95pandR99pare both small variations of the base indicator class defined in thebasessection:RXXp. The latter is similar tofirst_frost_daybut here thecomputeis not defined inxclimbut rather inexample.py. Also, the custom function returns two outputs, so theoutputsection is a list of mappings rather than a mapping directly. The two variations only change the variable names and inject a differentpercvalue.
Additionally, the YAML specified a realm and references to be used on all indicators and provided a submodule docstring.
Finally, French translations for the main attributes and the new indicators are given in example.fr.json. Even though new indicator objects are created for each YAML entry, non-specified translations are taken from the base classes if missing in the JSON file. The keys (indicator identifier) into this json file are case-insensitive.
Note that all files are named the same way : example.<ext>, with the translations having an additional suffix giving the locale name. In the next cell, we build the module by passing only the path without extension. This absence of extension is what tells xclim to try to parse a module (*.py) and custom translations (*.<locale>.json). Those two could also be read beforehand and passed through the indices= and translations= arguments.
Validation of the YAML file
Using yamale, it is possible to check if the YAML file is valid. xclim ships with a schema (in xclim/data/schema.yml) file.
The validation can be executed in a python session:
[ ]:
from importlib.resources import files

import yamale

data = files("xclim.data").joinpath("schema.yml")
schema = yamale.make_schema(data)

example_module = yamale.make_data(example_dir / "example.yml")  # in the example folder

yamale.validate(schema, example_module)
Or the validation can alternatively be run from the command line with:
yamale -s path/to/schema.yml path/to/module.yml
Note that xclim builds indicators from a yaml file, as shown in the next example, it validates it first.
Creating the collection
The IndicatorCollection is created through its from_yaml class method. Notice that all indicators created this way have the name of the module prepended to their identifier. For example, in the following example, the identifier of the indicator instance is example.R99p.
[ ]:
import xclim as xc

example = xc.IndicatorCollection.from_yaml(example_dir / "example", mode="raise")
[ ]:
docstring = f"{example.__doc__}\n---\nDocumentation for {example.R99p.identifier}\n\n{example.R99p.__doc__}"
display(Code(docstring, language="rst"))
Useful for using this technique in large projects, we can iterate over the indicators. IndicatorCollection inherits from the standard dictionary, so methods like items are available.
[ ]:
from xclim.testing import open_dataset

ds = open_dataset("ERA5/daily_surface_cancities_1990-1993.nc")
with xr.set_options(keep_attrs=True):
    ds2 = ds.assign(
        pr_per=xc.core.calendar.percentile_doy(ds.pr, window=5, per=75).isel(percentiles=0),
        prveg=ds.pr * 1.1,  # Very realistic
    )
    ds2.prveg.attrs["standard_name"] = "precipitation_flux_onto_canopy"

outs = []
with xc.set_options(metadata_locales="fr", as_dataset=True):
    inds = ["Indicators:"]
    for name, ind in example.items():
        print(f"computing {name}")
        out = ind(ds=ds2)  # Use all default arguments and variables from the dataset
        outs.append(out)
out contains all the computed data, with translated metadata. Note that this merge doesn’t make much sense with the current list of indicators since they have different frequencies (freq).
[ ]:
out = xr.merge(outs, join="outer", compat="override")
out.attrs["title"] = "Indicators computed from the example module."
out